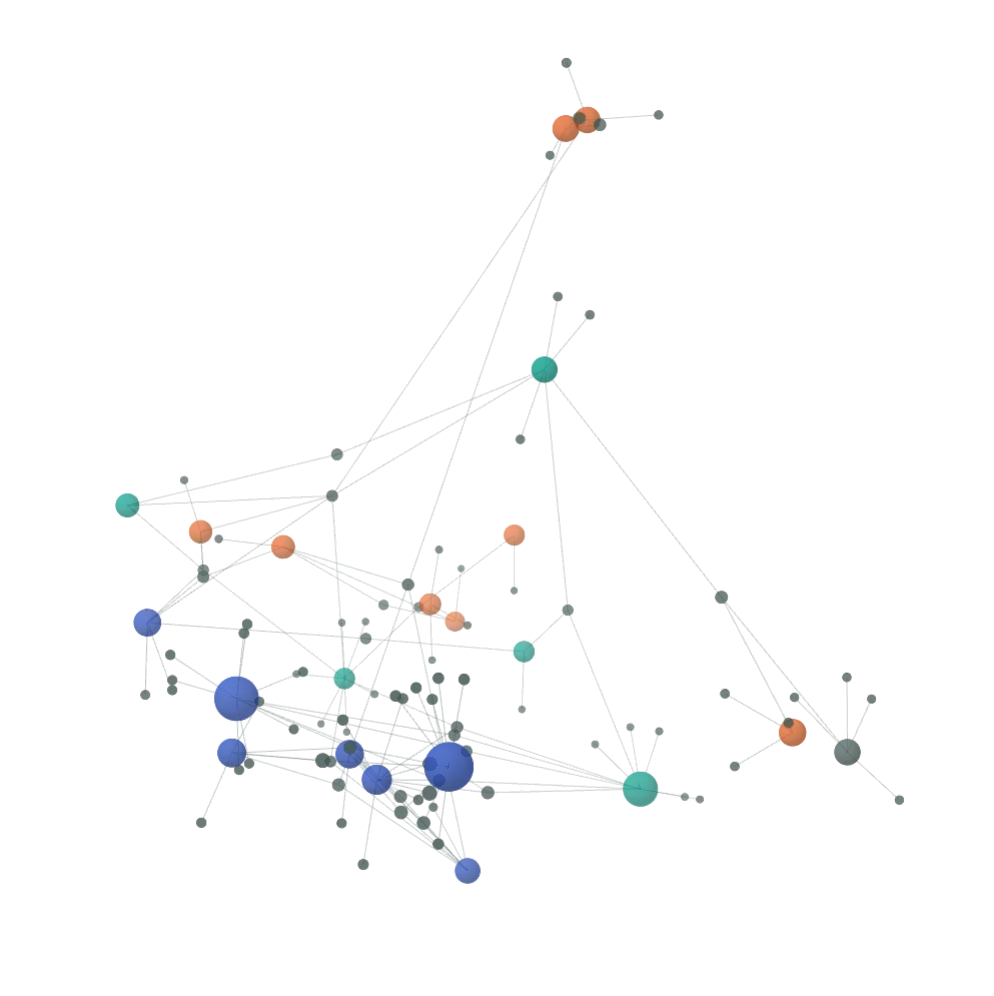
Ad Hoc Insights: Consumer GoodsAlmaImage Classification of BillionairesCredit Card Fraud Detection ModelCredit Risk ModelFood and Beverages OOP ConceptsLibraLink: Smart Attendance System with Book RecommendationMovie Recommendation System (Coursera course)Movie Recommendation SystemOutreach Mail GeneratorPatient’s Condition Classification Using Drug ReviewsPersonal Medical Chatbot with LLM RAGPlant Disease DetectionPySpark MLReport and Interview IntegrationResearch Assistant BotSimple Personal ChatbotSpeech Emotion RecognitionTwitter Sentiment AnalysisVision QCAI Voice Agent
21 projects, placed by embedding each description with all-MiniLM-L6-v2 and reducing to 3D with PCA. Press a field to label its projects. Browse all projects
Vision LLM system that checks fiber installation photos against an ISP's photo standards. The proof of concept won the tender, and production is underway.
12/2025 - presentAI Engineer - Intern02/2025 - 11/2025MaknadataJakarta, Indonesia
Developing a real-time conversational AI voice agent for sales roleplay training, building a cascaded voice pipeline (ASR → LLM → TTS) from scratch.
Implemented LLM tool calling to control each conversation turn, grounding responses in scenario facts through Qdrant vector retrieval (Vertex AI embeddings).
Built a multimodal LLM-as-judge pipeline scoring recorded sales conversations against a versioned rubric.
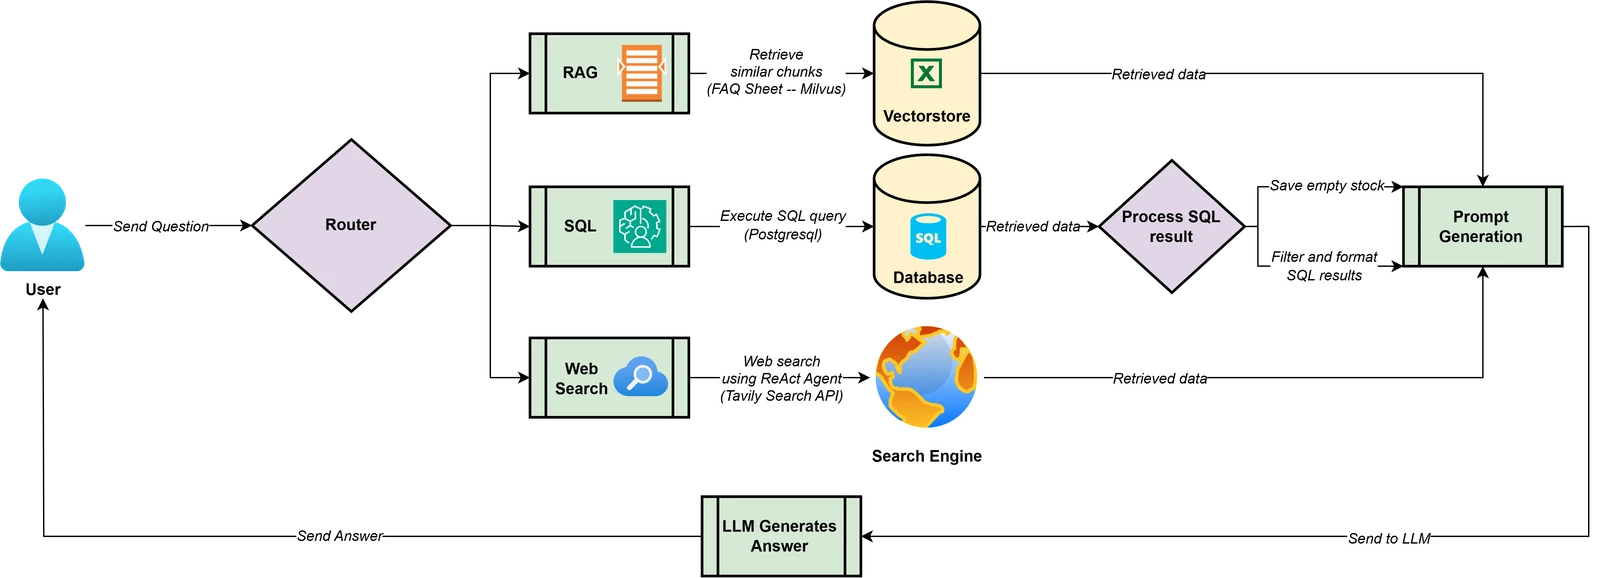
Built AI Agent (Agentic AI) system (RAG, text-to-SQL, etc.) with FastAPI and PostgreSQL backends, containerized using Docker.
Researching and benchmarking proprietary and open-source speech/language models to evaluate cost-efficiency and self-hosting feasibility, reducing dependency on third-party APIs.
Architected backends as layered DDD services with enforced module boundaries, and dispatched long-running evaluation jobs to Cloud Tasks workers on Cloud Run.
Implemented logging and monitoring (observability) for a compliance audit backend service.
Developed an automated system that merges draft reports and interview transcripts using LLMs, streamlining document integration and enhancing workflow efficiency.
Analyzed business use cases to identify opportunities for AI-driven solutions.
Tutor
09/2023 - 01/2024Bina Nusantara University
Conducted weekly study classes for Statistics and Linear Algebra, supporting students throughout one semester.
Facilitated learning by providing explanations, answering questions, and offering guidance to ensure student success in these subjects.
Project-Based Virtual Intern: Data Scientist
08/2023 - 09/2023ID/X Partners x Rakamin AcademyJakarta, Indonesia
Finishing various task related with the activity of Data Scientist from ID/X Partners, such as Big Data Fundamental, Statistics & Data Analytics, and Machine Learning Implementation.
Education
Master of Computer Science
Bina Nusantara University
2025 - present
Focus
Data Science
GPA
4.00 (latest)
Bachelor of Computer Science
Bina Nusantara University
2022 - 2025
Focus
Intelligent System
GPA
3.96
Honors
Dean’s List
More projects
AI agents, LLMs, RAG and voice
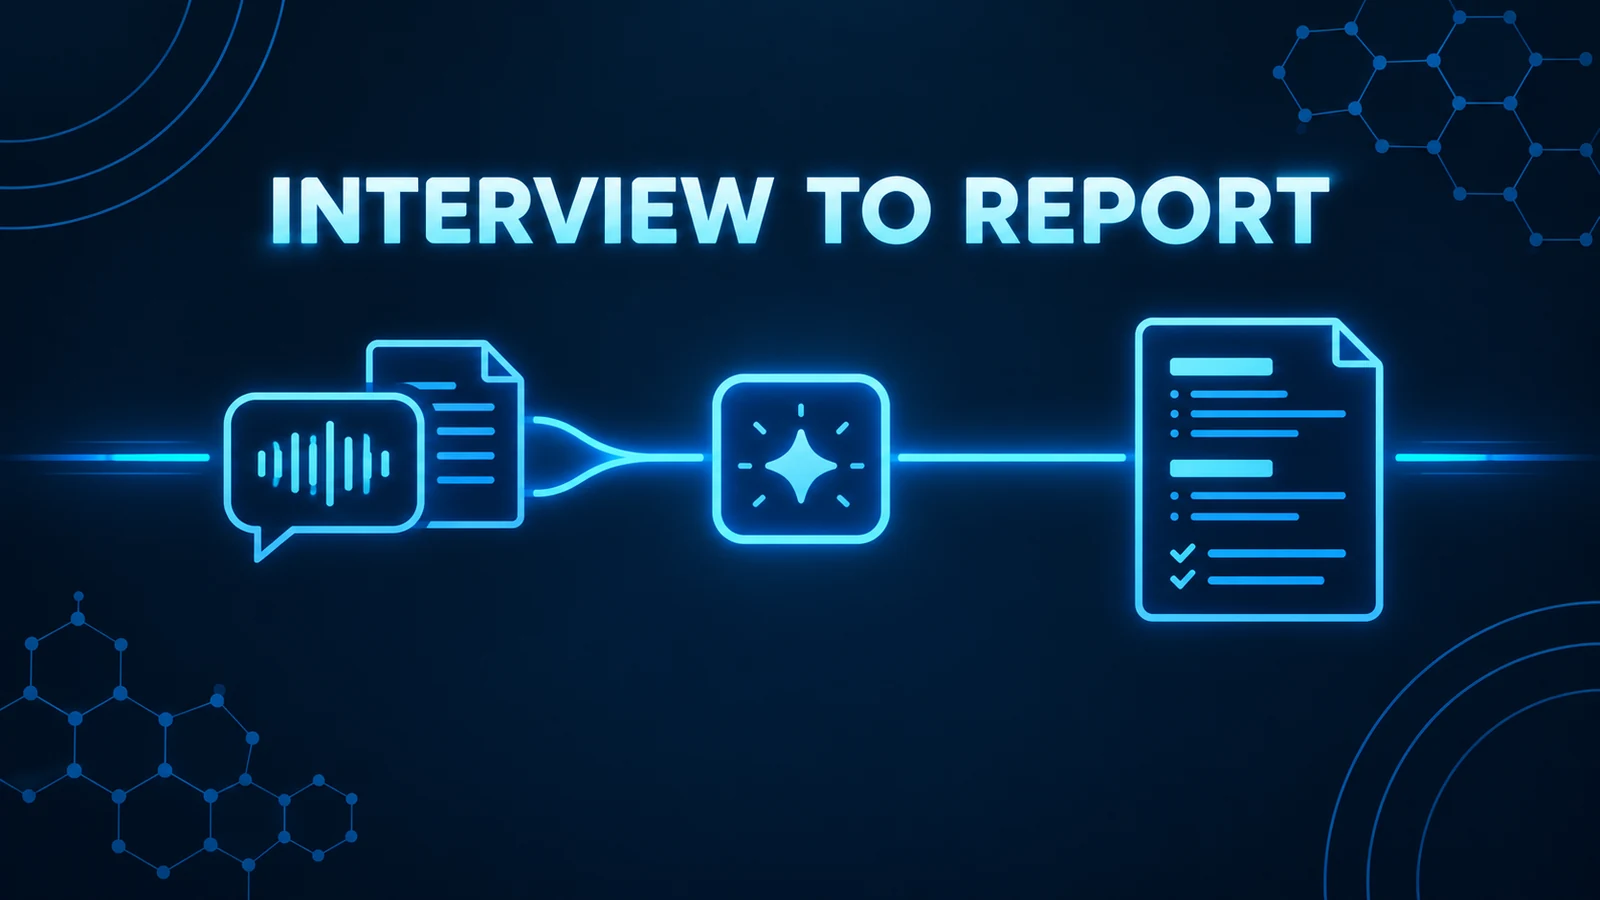
Report and Interview IntegrationClient work
AI platform that turns interview recordings and a draft into a structured assessment report. It transcribes the audio, merges the transcripts into the draft section by section, and writes an analysis of the interview.
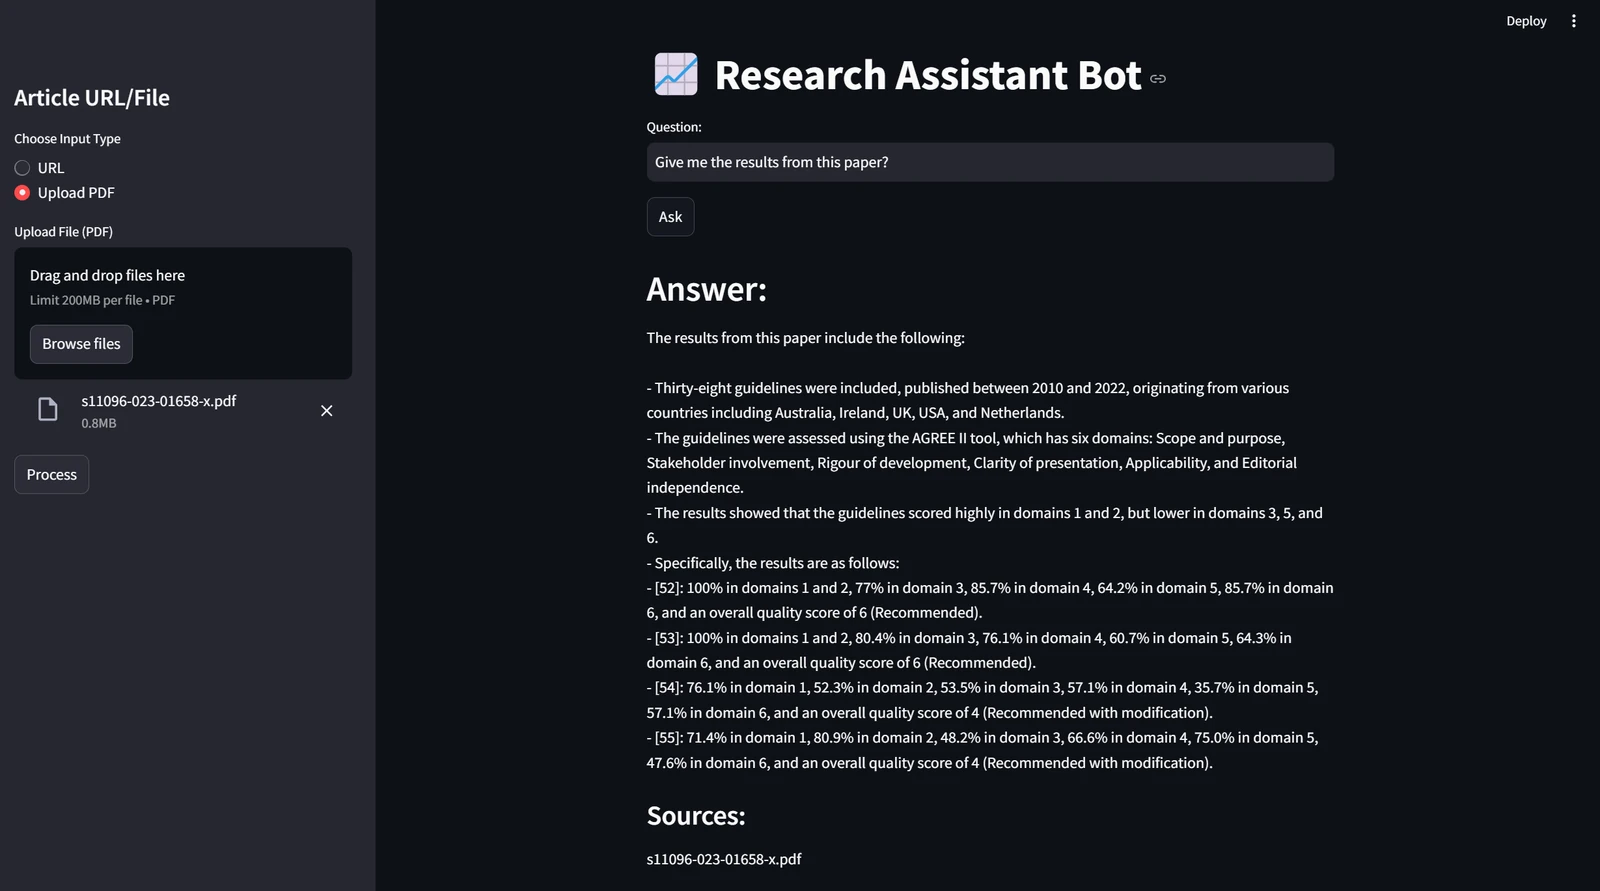
Research Assistant Bot (RAB) is a user-friendly research tool for retrieving information. Users can input article URLs or upload a PDF file and ask questions related to the content.
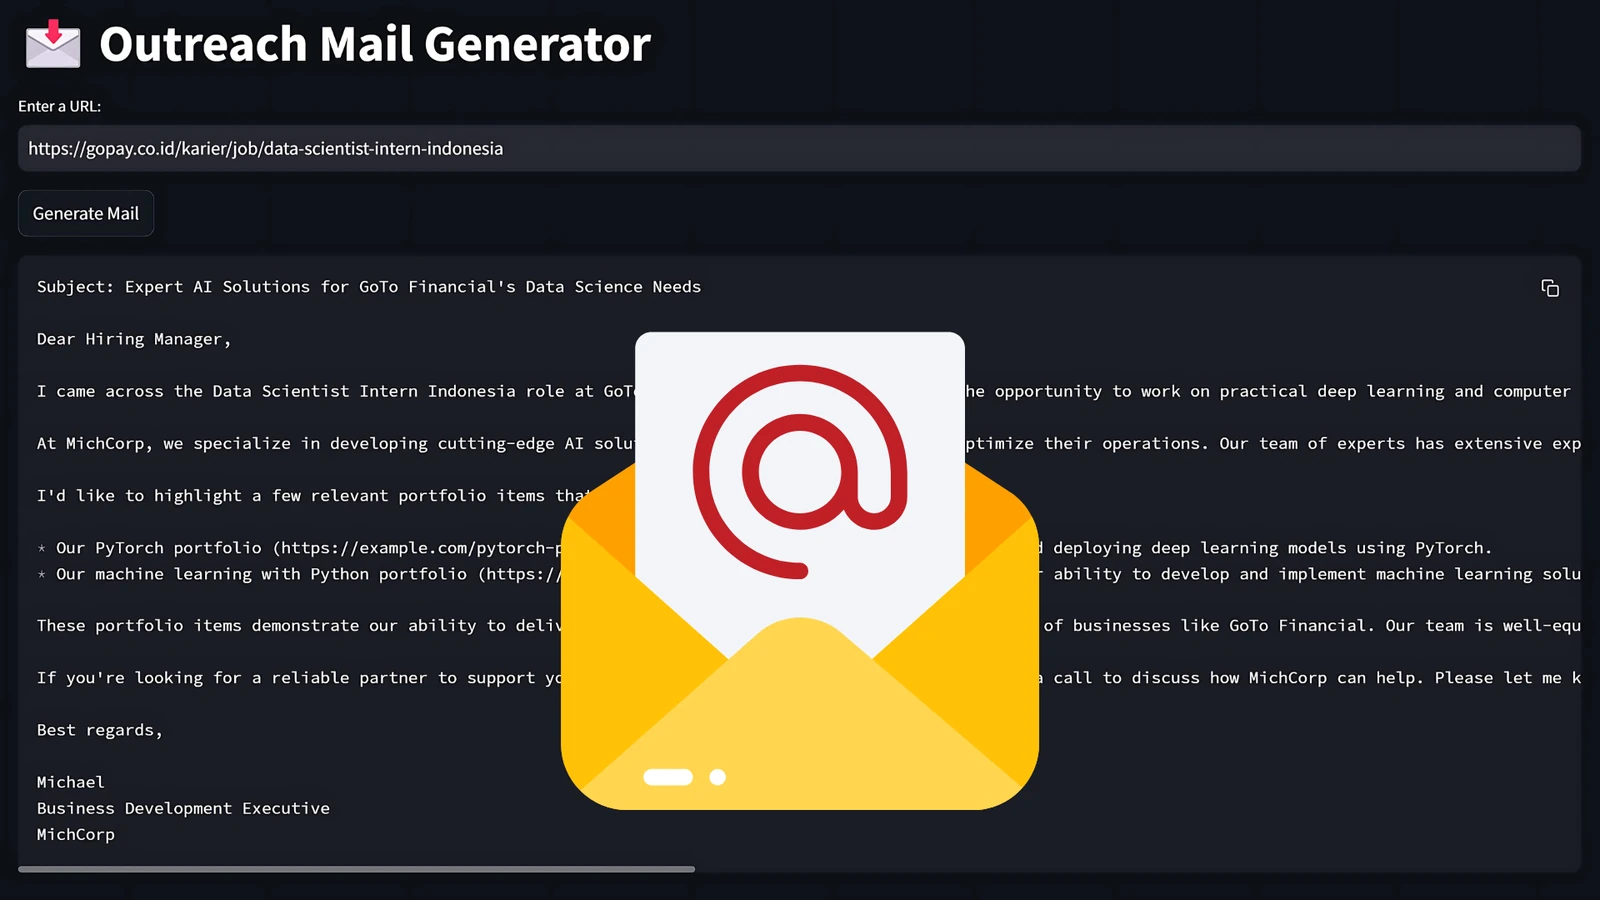
Outreach Mail Generator is a tool designed to help companies generate outreach emails using Groq, LangChain, ChromaDB, Llama-3.3-70B-Versatile, and Streamlit/Gradio. Users can input the URL of a company's careers page, extract job postings, and generate personalized emails. These emails include relevant portfolio links retrieved from a vector database, tailored to match specific job descriptions.
Personal medical chatbot project using Large Language Models (LLM) and Retrieval Augmented Generation (RAG). The chatbot retrieves medical information from PDF documents, employs LlamaCPP for LLM integration, and uses llama_index for efficient document handling. This approach enhances natural language responses and advanced information retrieval.
This simple personal chatbot project uses Artificial Neural Network (ANN) to process user queries, utilizing Flask and TensorFlow for development. It performs data preprocessing by tokenizing, removing punctuation and stopwords.
Tools: Rule-based, NLP, TensorFlow, Keras, Flask, ANN
This plant disease detection system uses traditional ML methods such as SVM and Random Forest with feature extraction techniques (Hu Moments, Haralick textures, and Color histograms) and pretrained CNNs such as ResNet50V2 and MobileNetV2. It includes a FastAPI backend with TensorFlow Serving. The model is deployed on Google Cloud Platform (GCP) using Cloud Functions and Cloud Storage, with an additional Gradio interface for easy access on Hugging Face Spaces.
Tools: TensorFlow, Keras, ResNet, MobileNet, TF Serving, FastAPI, Google Cloud Platform (GCP), Google Cloud Storage, Google Cloud Functions, Scikit-learn, Gradio
Speech Emotion Recognition (SER) using a Convolutional Neural Network (CNN). The project utilized datasets such as CREMA, RAVDESS, SAVEE, and TESS to train the model to classify various emotions from audio recordings.
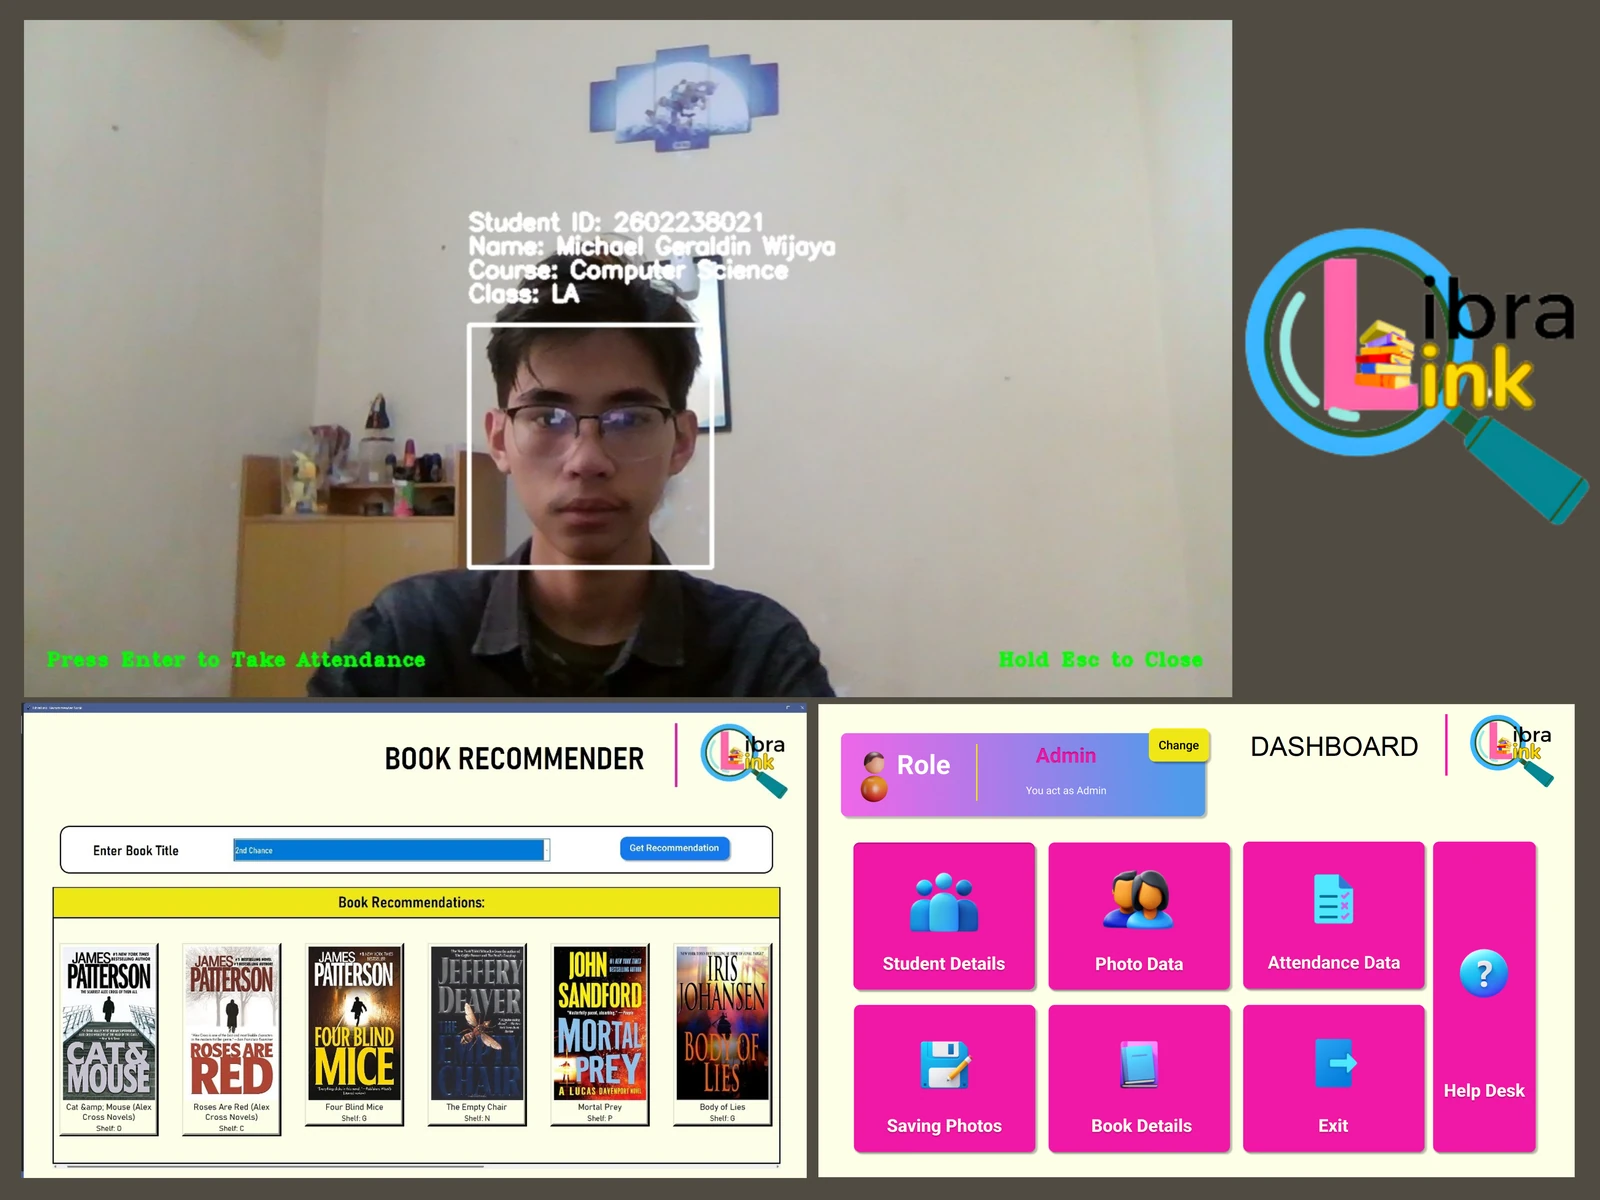
LibraLink: An advanced library system integrating facial recognition for attendance, using CNN or LBPH algorithms based on facial data patterns. It also features a book recommendation service, matching user preferences through the K-Nearest Neighbors (KNN) algorithm. The system uses MySQL as its relational database to manage and store student data.
Tools: TensorFlow, OpenCV, CNN, LBPH, KNN, Tkinter, MySQL
Machine learning model to detect credit card fraud using various algorithms such as Logistic Regression, Decision Tree, Random Forest, and XGBoost. This dataset is highly imbalanced, so several resampling techniques are applied to balance the data.
Patient condition classification using drug reviews applies multiple machine learning models such as Passive Aggressive Classifier, Random Forest, XGBoost, and etc. The project also applies text processing techniques including CountVectorizer, TFIDFVectorizer, and Word2Vec to analyze user reviews from a dataset. The project uses Streamlit for the user interface and deployment to provide a demo.
This project is a sentiment analysis of Twitter, where I use deep learning models like MLP and LSTM to classify tweets based on positive or negative sentiments.
This PySpark_ML repository focuses on data processing and machine learning, covering PySpark concepts such as data manipulation, transformation, and aggregation. It includes machine learning techniques using Spark's MLlib and ML libraries, with implementations of various regression and classification algorithms (e.g., random forest regressor, linear regression, logistic regression, naïve bayes, gradient boosting, and random forest classifier).
This ML project utilizes a Content-Based Recommender System for movies, using features like titles, genres, and posters to provide recommendations based on the chosen film.
These are assignments from a course in the Coursera Machine Learning Specialization, which involve implementing collaborative filtering and content-based filtering recommender systems using techniques such as matrix factorization and neural networks.
Comparative Analysis of Machine Learning Algorithms and Data Balancing Techniques for Credit Card Fraud Detection
Michael Geraldin Wijaya, Muhammad Faza Pinaringgi, Alfi Yusrotis Zakiyyah, Meiliana
Procedia Computer Science (Elsevier), vol. 245, pp. 677-688, 2024. Oral presentation at International Conference on Computer Science and Computational Intelligence (ICCSCI).
Supervised Machine Learning: Regression and Classification
DeepLearning.AI, 2024
ASEAN Data Science Explorers 2024 Enablement Session: SAP Analytics Cloud and SAP Build Apps Online Training Session
ASEAN Foundation, SAP, 2024
Advanced Python
Skilvul, 2024
Algorithm & Data Structures with Python
Skilvul, 2024
About
Michael Geraldin Wijaya
AI Engineer at Maknadata
Most people call me Gerald or Mich. I’ve always been curious about what data and AI make possible, and I build AI solutions for real problems: a process that runs faster, an answer that is easier to find, a decision made with better information.
I measure what I build before it ships, keep learning as the field moves, and enjoy working with people who share what they know. If you’d like to build something together, write to me below.
Contact
I’m open to new opportunities, collaborations, and questions about any of these projects. Send a message, or email me directly.